Lambda is joining the AI ecosystem at NVIDIA GTC Berlin 2026 around a shared set of priorities: making AI safer, more secure, and more efficient to run at scale.
We hear the same priorities from the teams building on Lambda. Workloads are shifting from single training runs to always-on inference and autonomous agents, and that shift brings new questions:
- How do you protect intellectual property and sensitive data on infrastructure you don't own?
- How do you let agents act without losing control?
- How do you get more tokens out of the same power envelope?
Lambda, the Superintelligence Cloud, is a Gold sponsor at GTC Berlin. We're sharing the progress we've made with NVIDIA on the security, reliability, and efficiency these workloads need.
1. Supporting Confidential Bare Metal with NVIDIA Confidential Computing
Frontier model builders increasingly rely on cloud providers to train and serve models at scale. Many prefer bare-metal access because it makes it easier to work across multiple providers. But running workloads on infrastructure they don't own makes protecting intellectual property and sensitive data a top priority.
Lambda is announcing support for Confidential Bare Metal, an expansion of NVIDIA Confidential Computing to dedicated third-party infrastructure. Hardware-rooted isolation and cryptographic attestation help protect models and data while they run, and let teams verify that the compute environment is trustworthy.
Alongside Confidential Containers and Confidential Virtual Machines, this lets frontier model builders deploy their software stack on bare-metal instances to meet their trust boundaries and operational requirements. NVIDIA Confidential Computing is also expanding across NVIDIA Grace Blackwell and NVIDIA Vera Rubin systems.
2. Advancing agent safety with the NVIDIA OpenShell Reference Architecture
In September, Lambda joined with NVIDIA to support open agent safety. With enforced limits on what agents can access, teams can give agents real permissions while staying in control.
Today, we're announcing support for the NVIDIA OpenShell Reference Architecture, which builds on the foundation of NVIDIA OpenShell secure runtime software and extends that foundation into full-stack, industrial-scale infrastructure for agent development and operations.
Building on our NVIDIA Vera Rubin investment, we're bringing together model compute, governed agent execution, and independent security enforcement. Because enforcement sits outside the agent's own execution environment, teams can expand what agents do while keeping control over the tools, data, and systems they can reach.
3. Enhancing infrastructure monitoring with NVIDIA Minerva
We're adamant that compute is not a commodity. AI campuses are complex to build and operate, and the stakes grow with the cluster: a single degraded component can slow or stall an entire workload.
Lambda plans to deploy NVIDIA Minerva, an AI for IT operations (AIOps) platform that connects telemetry across GPUs, networking, storage, schedulers, and AI workloads. Its dynamic knowledge graph maps infrastructure components to running jobs, while specialized AI models detect anomalies, predict emerging failures, and correlate related alerts to identify likely root causes.
For our users, the goal is fewer workload interruptions, faster fixes, higher goodput, and more tokens produced.
4. Increasing token throughput with NVIDIA DSX MaxLPS
Power is becoming a major constraint on AI infrastructure. In a proof of concept on NVIDIA HGX systems, Lambda used NVIDIA DSX MaxLPS software to run 19 nodes within the same aggregate power budget as a 16-node baseline, with ~24% higher cluster-wide token throughput and ~23% higher performance per watt.
Read more about the proof of concept in this NVIDIA case study with Lambda.
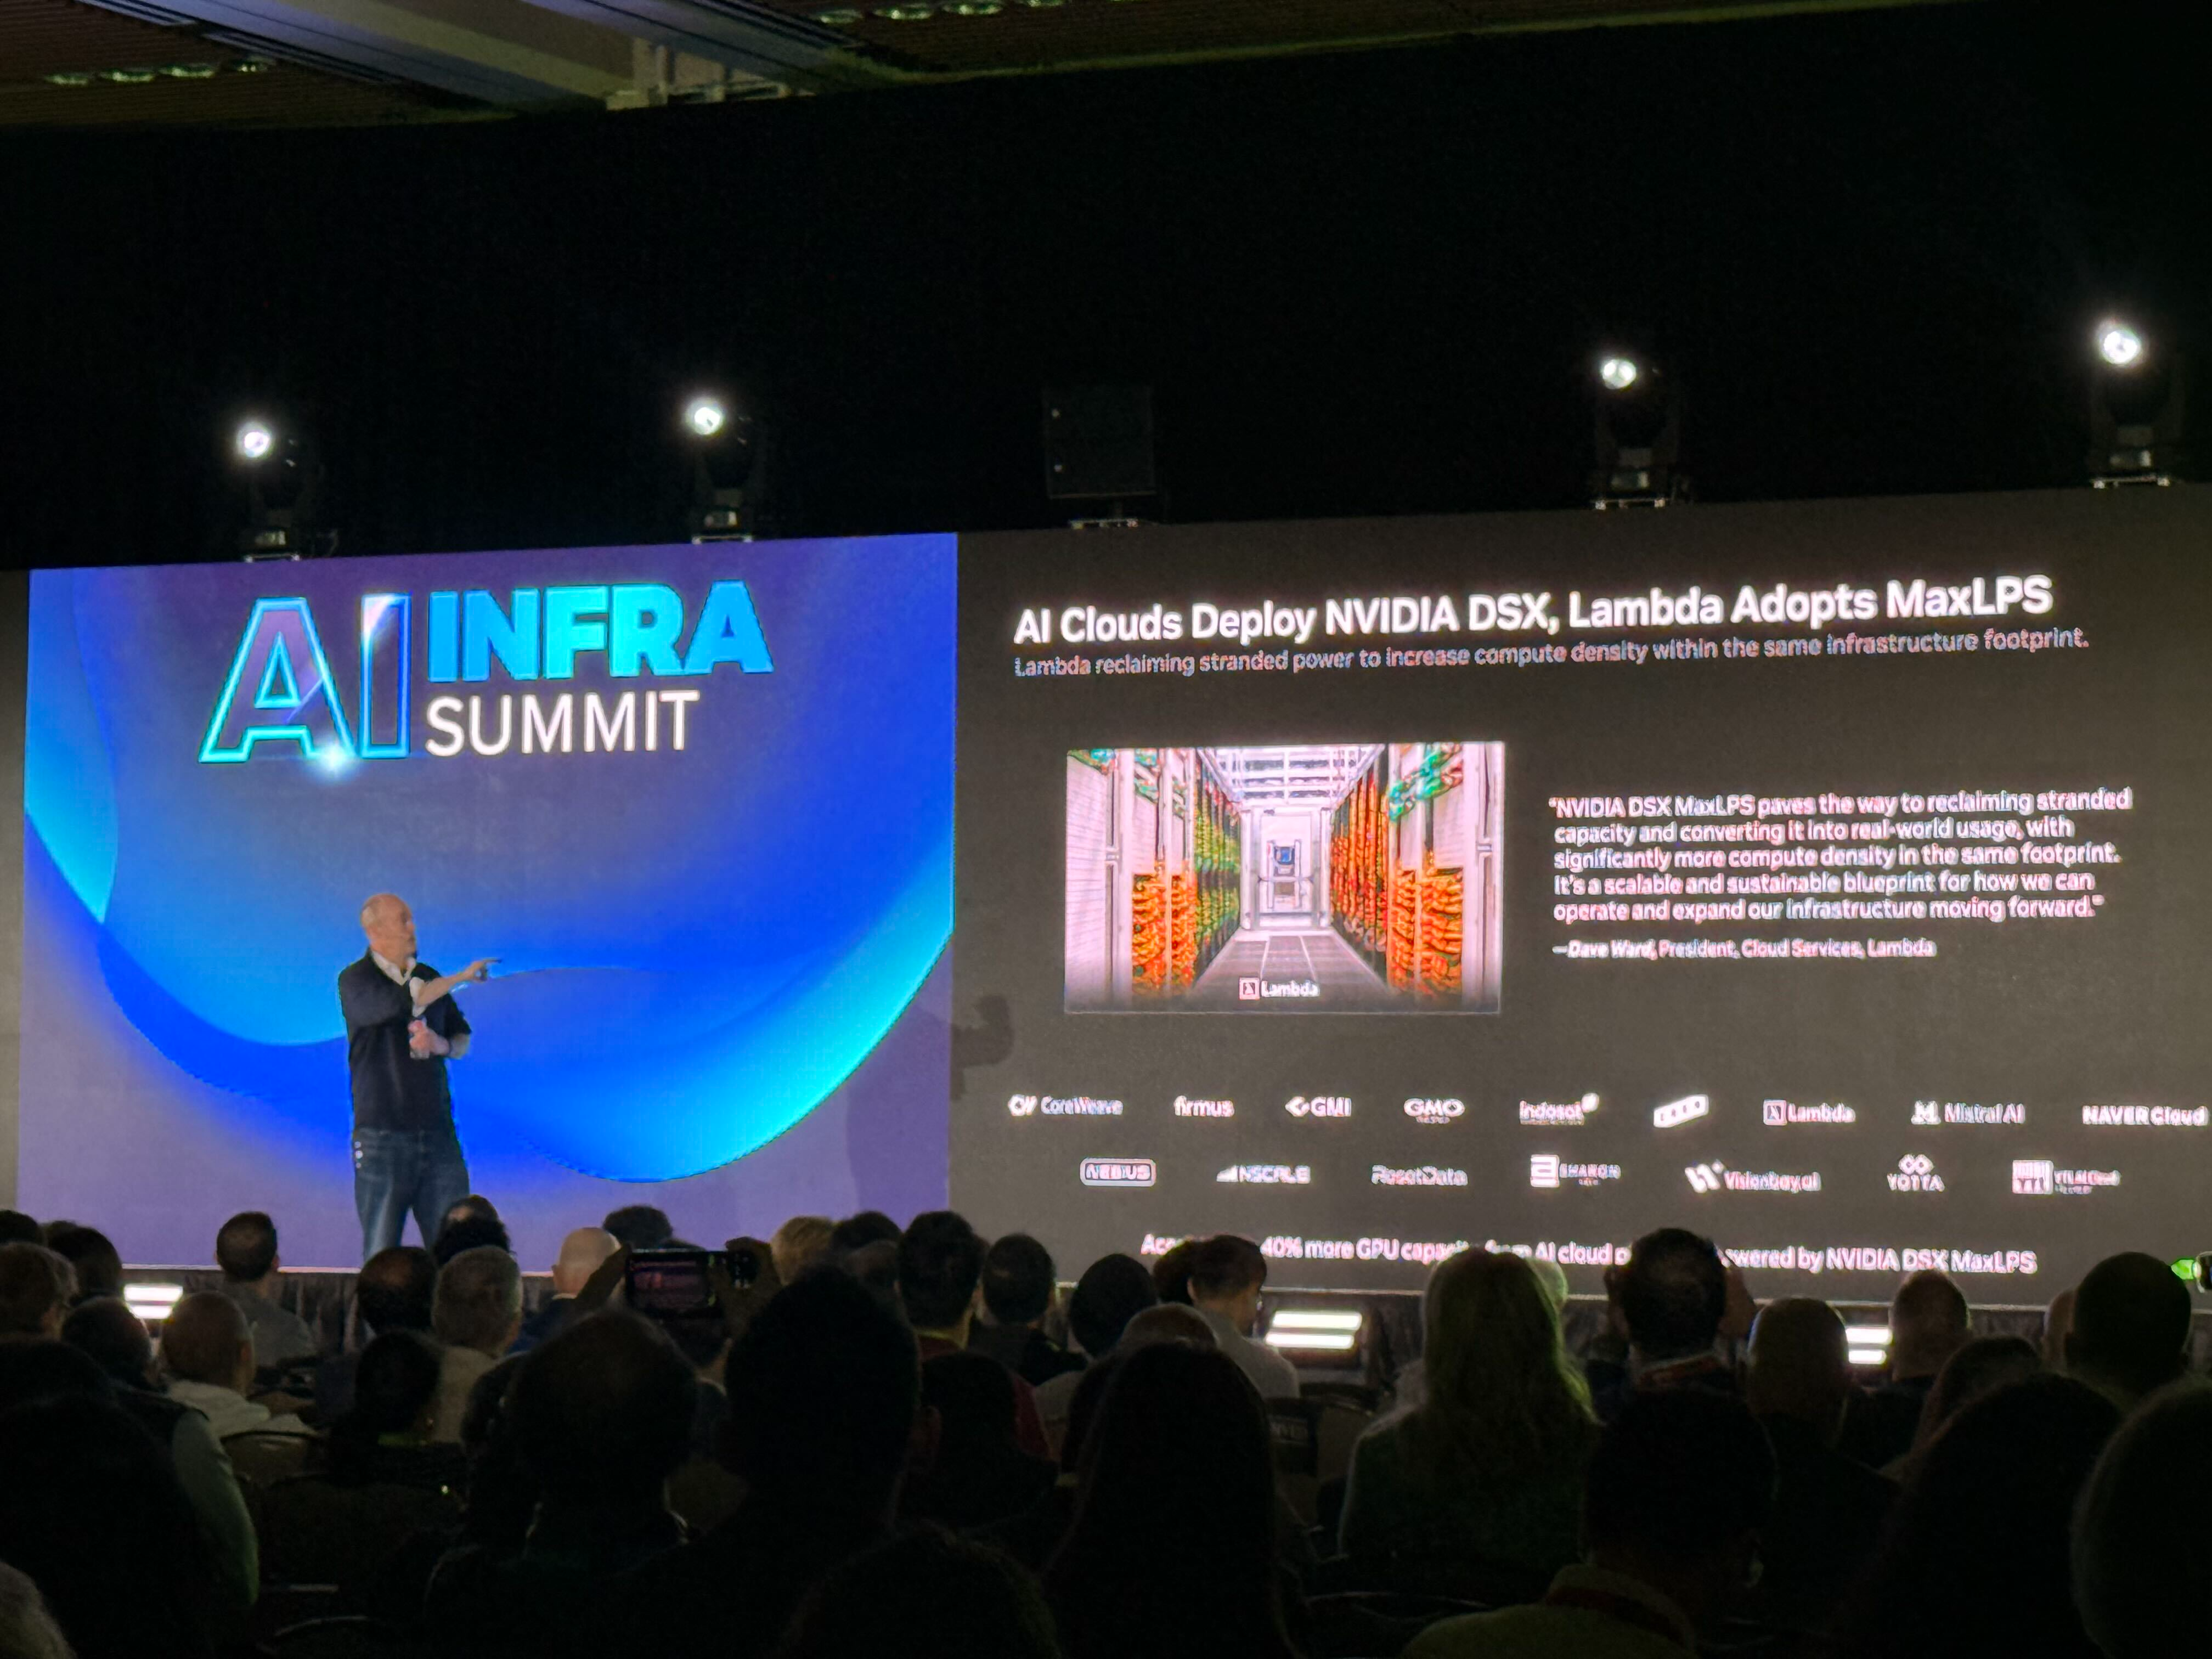 Ian Buck, Vice President of Hyperscale and High-Performance Computing at NVIDIA, during his keynote at AI Infra Summit 2026
5. Bringing it together at our booth
Across security, agent safety, reliability, and efficiency, we're working with NVIDIA to help AI teams protect workloads, keep control of agents, and get more from their infrastructure.
Find the Lambda team at booth 7022 all week:
- See NVIDIA Nemotron and OpenShell in action in our demos.
- Talk through capacity, deployment, and production-readiness decisions.
- Ask about Lambda's offer for NVIDIA Inception members.
See you in Berlin.